Anurag Renduchintala*, Adi Mahesh*, Zichen Zhang*, Zimo Si*, Shangjun Meng*, Samuel Fang*.
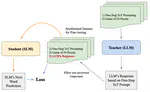
Tree-of-Thoughts can solve hard reasoning problems by exploring and backtracking across multiple paths, but its repeated prompts are expensive and poorly suited to small models. We compressed it into one structured prompt and distilled
GPT-4o outputs into
SmolLM-360M. On Game of 24, One-Step ToT reached 19% accuracy versus 7% for Chain-of-Thought, while fine-tuning on 144 examples raised SmolLM from 1% to 9%. Our full GPT-4o Multi-Step ToT run reached 82%, above the prior 74% GPT-4 result.